SAIF: A Sparse Autoencoder Framework for Interpreting and Steering Instruction Following of Language Models
ECML 2026
Overview
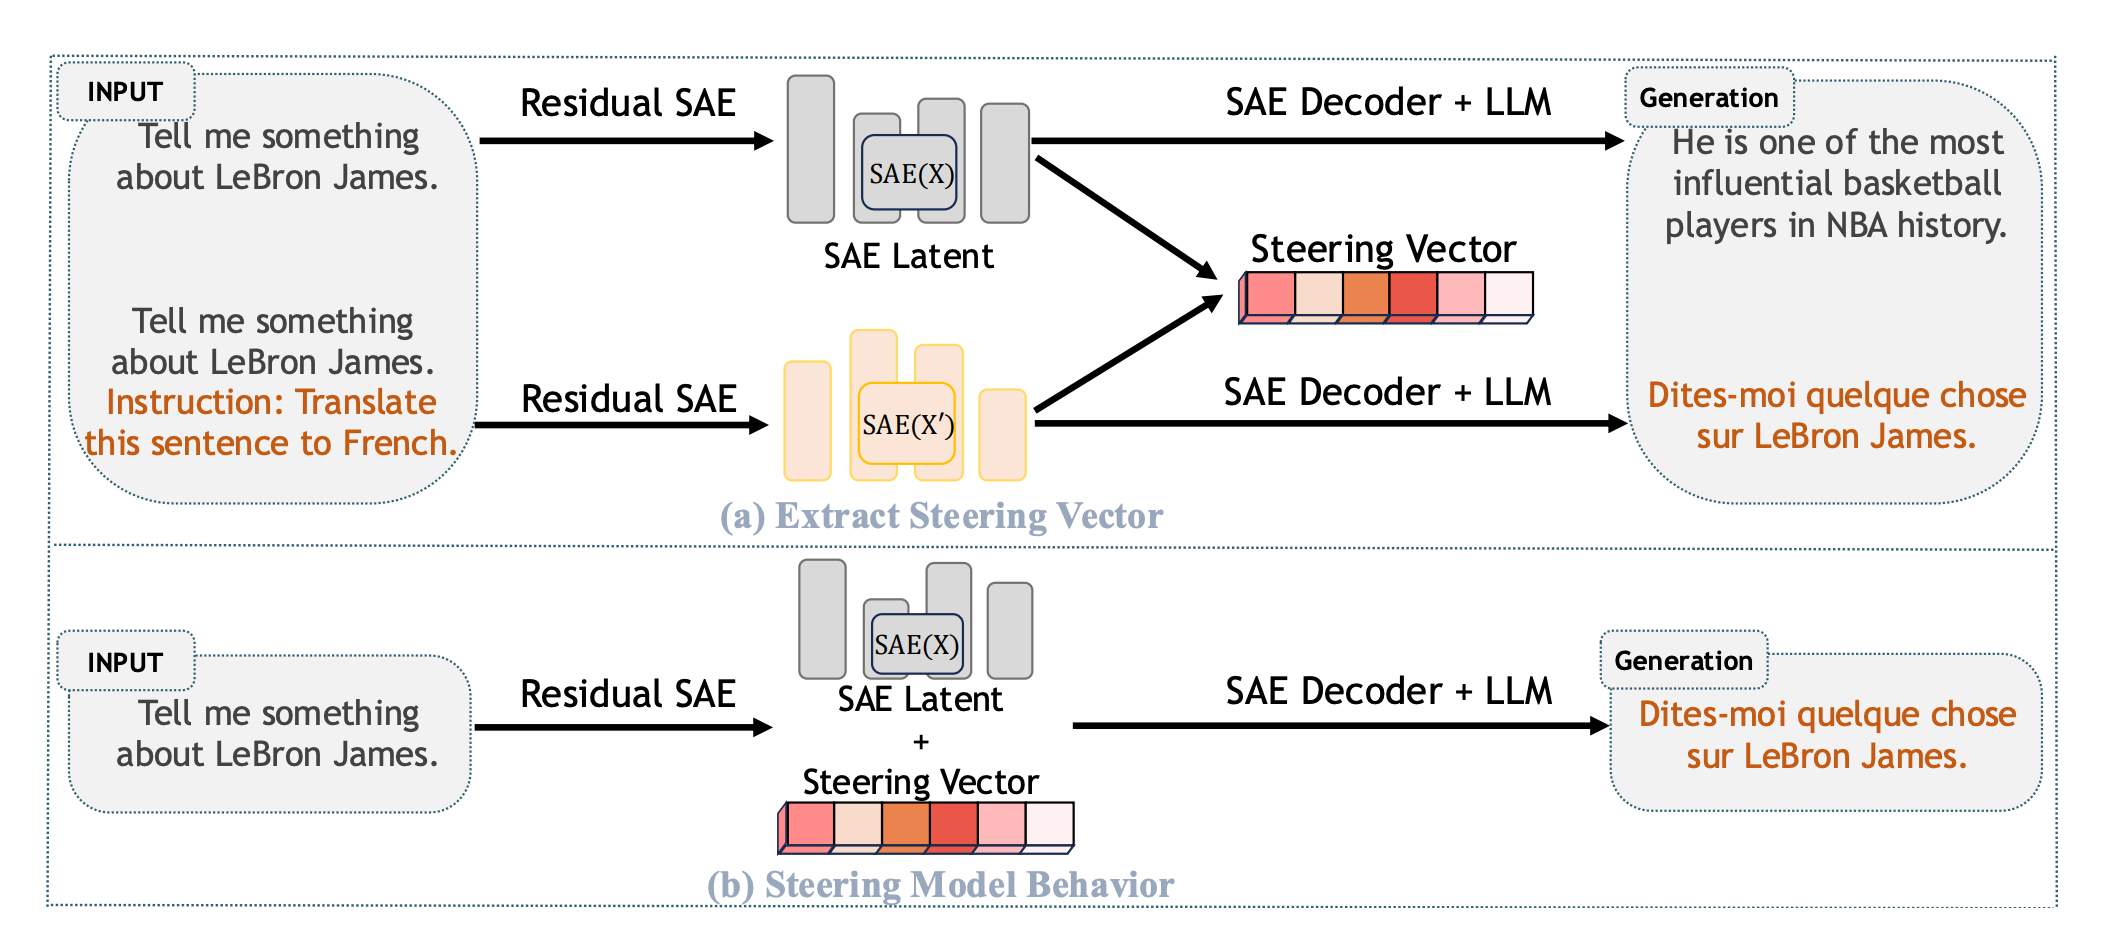
SAIF uses sparse autoencoders to study how language models follow instructions. It identifies instruction-relevant latent features and tests whether intervening on those features changes model behavior.
The analysis examines the semantic relationship between latent features and instructions, their causal effect on generated responses, and the conditions that affect steering, including feature selection, model layer, and instruction placement.
Results
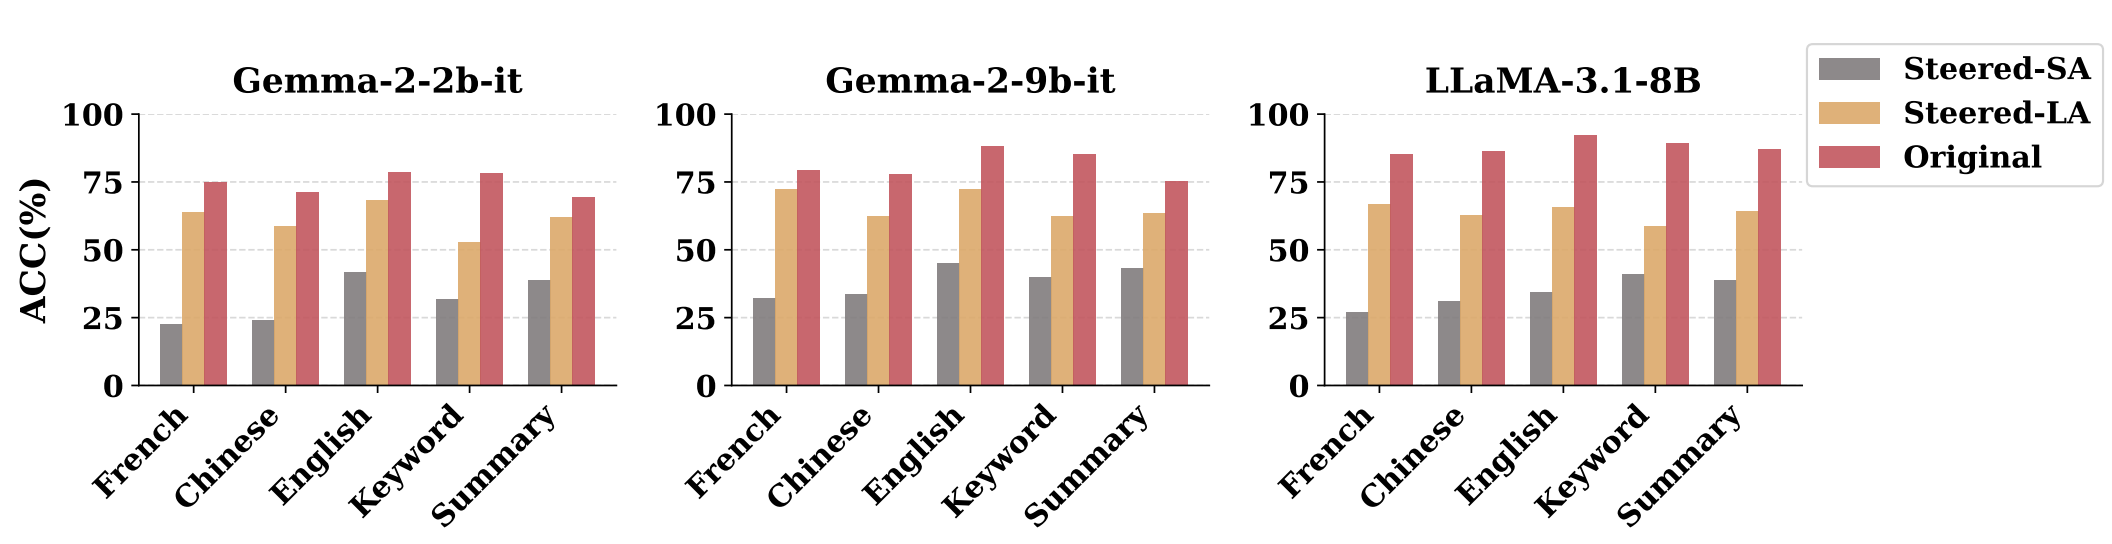
The paper reports that a distinct set of sparse autoencoder latents is associated with instruction-following behavior. The identified features are semantically related to instructions and can steer responses when activated. Experiments examine how these findings transfer across autoencoders and language models of different sizes.
BibTeX
@inproceedings{he2026saif,
  title={SAIF: A Sparse Autoencoder Framework for Interpreting and Steering Instruction Following of Language Models},
  author={He, Zirui and Zhao, Haiyan and Qiao, Yiran and Yang, Fan and Payani, Ali and Ma, Jing and Du, Mengnan},
  booktitle={European Conference on Machine Learning (ECML)},
  year={2026},
  eprint={2502.11356},
  archivePrefix={arXiv}
}